C2 Fit Statistics
Vig_2.RmdVignette 2: C2 Fit Statistic
The C2 fit statistic is the latest approach to evaluating absolute model fit with latent variable models. See extensive literature on this (TO DO).
- Generate ordinal data
- Compute C2 statistic
- Plot observed probabilities vs model-implied probabilties
- TODO: resolve which RMSEA confidence interval computation is correct
Generate data with only ordinal items. Use 5 items and 1 timepoint with N=500 to keep things simple and because C2 run-times are very long.
Specify Details of Data Generation
- Specify the item.types (note that this implicitly specifies the number of items)
- Specify how many categories in the items
- If it’s a categorical/count item, specify number of categories - if it’s continuous (e.g., Normal or Beta distribution), just set to
NA - Specify the Q-matrix
library(CLCM)
N <- 500
number.timepoints <- 1
item.type <- rep('Ordinal', 5)
sim.categories.j <- c(4, 2, 2, 2, 4)
lc.prop <- list('Time_1' = c(0.5, 0.5))
Q <- matrix(1, nrow = length(item.type), ncol = 1,
            dimnames = list(paste0('Item_', 1:length(item.type)), NULL))
Q
#>        [,1]
#> Item_1    1
#> Item_2    1
#> Item_3    1
#> Item_4    1
#> Item_5    1
This Q-matrix indicates a single attribute/factor (K=1) will be generated, creating 2 latent classes. Note: the simulation function has a default of 2 latent classes - we’ve just re-created the default Q-matrix.
In summary, 5 ordinal items will be generated, 2 of which have 4 categories, and 3 of which have 2 categories. The latent class proportions will be divided evenly, 50/50, across both latent classes. Only cross-sectional data will be generated. Let’s keep things simple because the C2 statistic is computationally burdensome to compute.
Simulate Item Responses
set.seed(03062021)
sim.dat <- simulate_clcm(N = N, Q = Q, number.timepoints = number.timepoints,
                         item.type = item.type,
                         categories.j = sim.categories.j,
                         lc.prop = lc.prop)
Estimate CLCM
Estimate the model:
mod <- clcm(dat = sim.dat $dat,
            item.type = sim.dat $item.type,
            item.names = sim.dat $item.names,
            max.diff = 0.001,
            Q = sim.dat$Q)
#> iteration:  1   max diff in item parameter estimates:  0.986824
#> iteration:  2   max diff in item parameter estimates:  0.287047
#> iteration:  3   max diff in item parameter estimates:  0.164523
#> iteration:  4   max diff in item parameter estimates:  0.095628
#> iteration:  5   max diff in item parameter estimates:  0.056996
#> iteration:  6   max diff in item parameter estimates:  0.035052
#> iteration:  7   max diff in item parameter estimates:  0.022075
#> iteration:  8   max diff in item parameter estimates:  0.014072
#> iteration:  9   max diff in item parameter estimates:  0.008969
#> iteration:  10   max diff in item parameter estimates:  0.006492
#> iteration:  11   max diff in item parameter estimates:  0.004711
#> iteration:  12   max diff in item parameter estimates:  0.003381
#> iteration:  13   max diff in item parameter estimates:  0.002301
#> iteration:  14   max diff in item parameter estimates:  0.001612
#> iteration:  15   max diff in item parameter estimates:  0.001268
#> iteration:  16   max diff in item parameter estimates:  0.001385
#> iteration:  17   max diff in item parameter estimates:  0.000864
Model Fit
After fitting the model, let’s proceed to look at absolute fit statistics. The C2 statistic is slow to compute because of the numerical jacobian that is computed. Or at least I think that’s why.
mod.fit <- C2_clcm(mod)
#> C2 = 5.038   P-Value = 0.411   RMSEA = 0.045
As you’d expect, the model-fit statistic indicates that the model fits the data.
Plots
Plot Model Implied Probabilities vs Observed Probabilities
p.mod <- mod.fit$p.mod
p.obs <- mod.fit$p.obs
p.range <- range(p.mod, p.obs)

#
plot(p.mod, ylim = p.range, xlab = paste0(nrow(p.mod), ' model-implied probabilities'),
     ylab = 'Probability', main = 'Model-Implied Probabilities')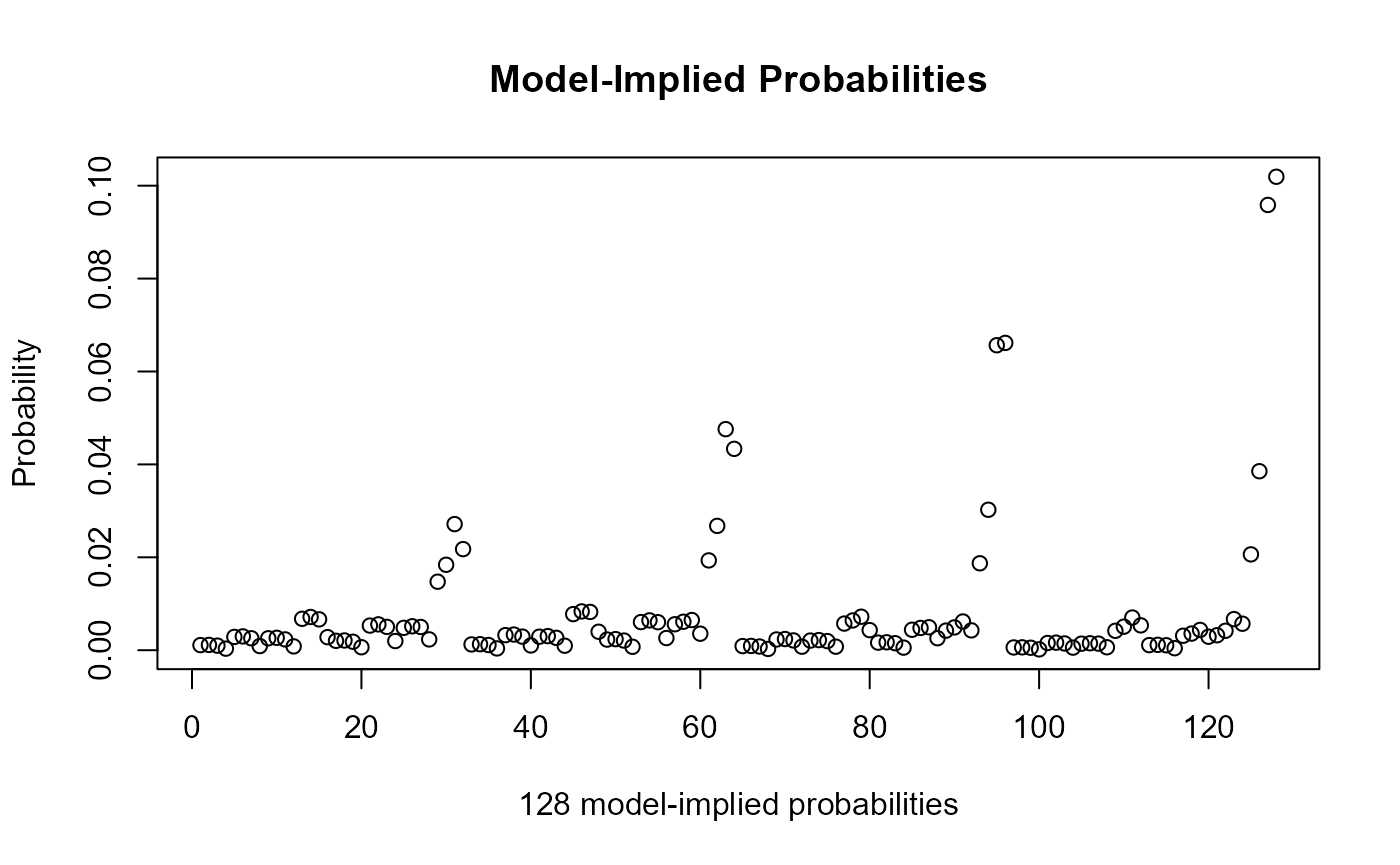
#
plot(p.obs, ylim = p.range, xlab = paste0(nrow(p.obs), ' observed probabilities'),
     ylab = 'Probability', main = 'Observed Probabilities')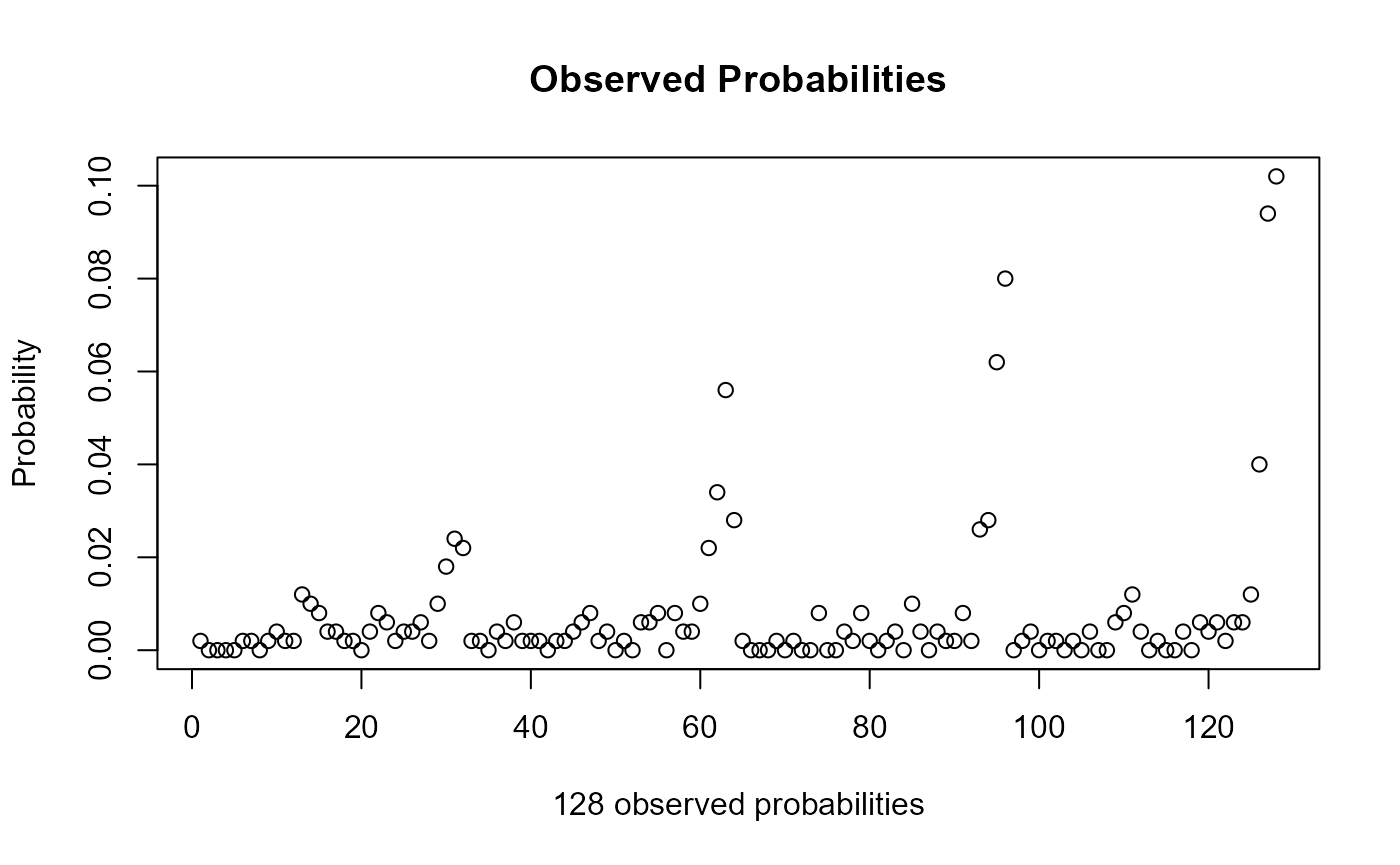
#
plot(x = p.obs, y = p.mod, main = paste0(nrow(p.mod), ' Probabilities'),
     ylim = p.range, xlim = p.range,
     xlab = 'Observed Probabilities', ylab = 'Model-Implied Probabilities')
abline(a = 0, b = 1)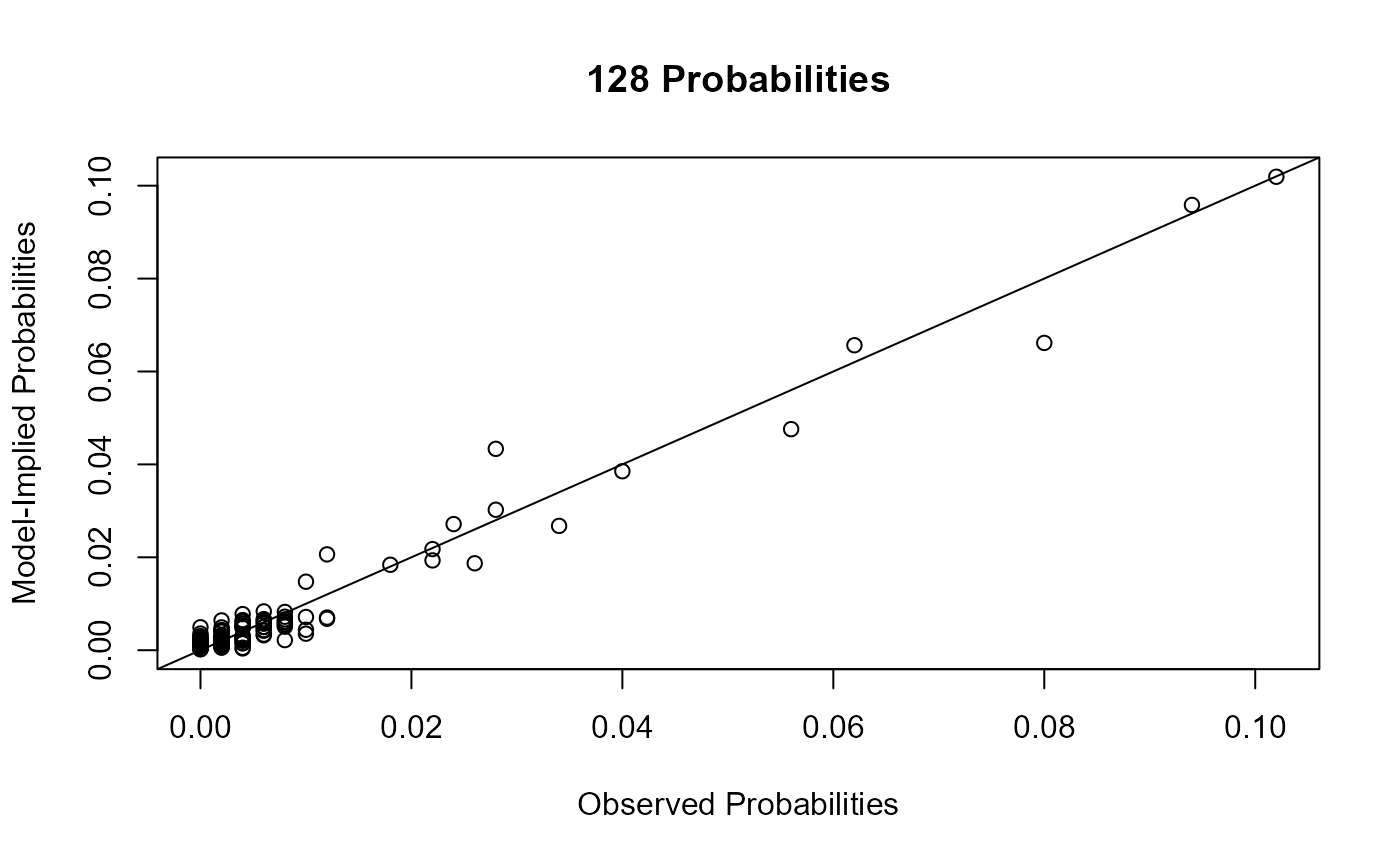
TODO Compare the confidence interval options.
Option 1: mirt R package RMSEA.CI function: # https://github.com/philchalmers/mirt/blob/master/R/utils.R Function is pasted below - load that first
Option 2: MBESS R package ci.rmsea function: https://github.com/cran/MBESS/blob/master/R/ci.rmsea.R
Option 3: GAIPE R package https://rdrr.io/cran/GAIPE/src/R/CI.RMSEA.R
library(mirt)
mirt::RMSEA.CI(X2 = mod.fit$C2, mod.fit$df, mod.fit$N, ci.lower=.05, ci.upper=.95)
# Not exported, it's part of the M2() function
# Have to pull it from github and copy/paste/run on your own

# Option 2:
library(MBESS)
MBESS::ci.rmsea(rmsea = mod.fit$rmsea, df = mod.fit$df, N = mod.fit$N, conf.level = 0.95)

# Option 3:
library(GAIPE)
GAIPE::CI.RMSEA(rmsea = mod.fit$rmsea, df = mod.fit$df, N = mod.fit$N, clevel = 0.95)
Below is the function from the mirt R package:
# # mirt R package
# # https://github.com/philchalmers/mirt/blob/master/R/utils.R
#

RMSEA.CI <- function(X2, df, N, ci.lower=.05, ci.upper=.95) {

    lower.lambda <- function(lambda) pchisq(X2, df=df, ncp=lambda) - ci.upper
    upper.lambda <- function(lambda) pchisq(X2, df=df, ncp=lambda) - ci.lower

    lambda.l <- try(uniroot(f=lower.lambda, lower=0, upper=X2)$root, silent=TRUE)
    lambda.u <- try(uniroot(f=upper.lambda, lower=0, upper=max(N, X2*5))$root, silent=TRUE)
    if(!is(lambda.l, 'try-error')){
        RMSEA.lower <- sqrt(lambda.l/(N*df))
    } else {
        RMSEA.lower <- 0
    }
    if(!is(lambda.u, 'try-error')){
        RMSEA.upper <- sqrt(lambda.u/(N*df))
    } else {
        RMSEA.upper <- 0
    }

    return(c(RMSEA.lower, RMSEA.upper))
}